Most Node.js HTTP services run single-process by default. The common fix is an
external process manager: a daemon, a CLI, a config file, and a resident memory
bill that scales with nothing your users do. The alternative has existed in the
Linux kernel since 3.9 and in Node.js since v22.12: SO_REUSEPORT — multiple
sockets bound to the same port, the kernel distributing connections between
them.
Almost nobody uses it, for a defensible reason: SO_REUSEPORT distributes
connections and nothing else. It has no opinion about crash loops, drain,
health, or sizing. The missing half — supervision — is why the daemon exists.
This article separates the two concerns: what the kernel changes about dispatch
topology, and what still has to be engineered around it. The reference
implementation is ClusterKit, an embedded orchestrator I built to make that
split concrete, but the topology reasoning holds whether you use native
cluster, an application server, or stay single-process behind a Deployment.
Table of contents
Open Table of contents
At a Glance
Audience. Tech leads and senior fullstack engineers running Node.js HTTP services on multi-core hosts — bare metal, VMs, or a multi-core pod limit.
Assumes. Node >= 22.12, an HTTP server, a Linux deploy target for the kernel path.
Not for. Framework choice, autoscaler tuning, or multi-application runtimes.
Maturity. Field-tested.
Improves. Dispatch-topology vocabulary, crash and shutdown semantics, orchestrator trade-off reasoning, and the pods-versus-workers sizing decision.
Does not solve. Request routing, TLS termination, or composing several applications into one deployment.
Three ways a connection reaches a worker
Multi-worker Node.js HTTP has exactly three dispatch topologies:
1. accept-on-connection (native cluster default). The primary accepts,
then passes the socket to a worker over IPC. Every connection pays a hop
through one process — and that process is now part of your data path. If it
saturates, the whole fleet saturates.
2. External dispatch (daemon or proxy). A process manager or reverse proxy owns the listen socket. Same shape, different owner: one extra hop, one extra process to run, patch, and restart.
3. Kernel dispatch (SO_REUSEPORT). Every worker binds the same (host,
port). The kernel distributes incoming connections across the listening
sockets, hashed by connection tuple — the same client lands on the same worker
for the life of the connection. There is no primary in the data path.
The third option changes two production properties:
- Crash visibility. A worker that dies closes its socket; the kernel simply stops delivering new connections to it. The surviving workers were never involved — there is no shared scheduler to become the bottleneck or the blast radius.
- Shutdown semantics. A draining worker stops being scheduled the moment its socket closes. Rolling restarts become a fleet-management problem, not a proxy-configuration problem.
What the kernel does not solve
SO_REUSEPORT is a distribution mechanism, not a supervision policy. Left
alone, here is what breaks first:
| Failure | What happens without supervision |
|---|---|
| Crash loop | Immediate re-fork under load → thundering restarts. You need backoff and a circuit breaker. |
| SIGTERM | Workers exit mid-request. You need drain with an ACK, then escalation (SIGTERM → SIGINT → SIGKILL). |
| Rolling restart | New worker up before old one drained → connection resets. You need a bounded handover. |
| Wedged worker | The event loop stops answering but the socket stays open; the kernel keeps sending it connections. You need health checks. |
| Container sizing | os.cpus() lies inside a cgroup limit. You need cgroup-aware sizing. |
That table is the actual product surface: distribution is one line of kernel
behavior; the other five rows are engineering. A daemon centralizes them. An
embedded library makes them part of main().
Isn’t Kubernetes the process manager?
The reflex is healthy: Kubernetes restarts failed containers, routes traffic, scales replicas — a process supervisor inside the pod looks like double bookkeeping. The reflex answers a different question. Every layer of the platform supervises containers. None of them supervises processes:
| Concern | Who handles it |
|---|---|
| Place pods on machines | the scheduler |
| Replace a pod after a node failure | kubelet + Deployment |
| Roll a new version across the fleet | Deployment rolling update |
| Distribute connections across pods | the Service (kube-proxy, eBPF…) |
| Distribute connections across cores | the kernel (SO_REUSEPORT) |
| Replace a crashed or wedged process without killing the container | nothing, by default |
That last row is where the robustness lives. When a worker dies, the kernel stops delivering connections to it instantly — no probe to fire, no shared state to corrupt — and the supervisor forks a replacement with deliberate backoff (~1 s, ~3 s measured; full fleet restore in ~3.6 s), in-flight requests of the draining worker completed, 35 requests served in the degraded window, zero timeouts. The pod never left the Service. The same failure in a single-process pod is a container restart: full cold boot behind a readiness gate, in-flight requests cut by the SIGTERM unless the app drains them itself, and if the crash repeats, kubelet’s exponential backoff — 10 s, 20 s, 40 s… up to 5 minutes — while the other replicas absorb the gap. The unit of failure becomes smaller than the unit of billing.
There is also a utilization question the platform never asks, because it assumes the answer. A pod is an allocation; Node is one event loop on one core. A 4-vCPU pod running single-process Node handles requests on a quarter of its reservation — “one process per container” quietly assumes the runtime cannot use the rest. The honest alternative is not “let Kubernetes handle it”: it is 1-vCPU pods. Same compute, different shape:
| 4 pods × 1 vCPU | 1 pod × 4 vCPU, 4 workers | |
|---|---|---|
| Compute | same | same |
| Pod IPs, sidecars, per-pod plumbing | ×4 | ×1 |
| Burst before autoscaling reacts | queueing latency for tens of seconds | workers already warm |
| One slice crashes | container restart, kubelet backoff | worker replaced in seconds, pod Ready |
| Autoscaling granularity | 1 core at a time | 4 cores at a time |
And the load balancing composes instead of competing: the Service hashes connections across pods, the kernel hashes them across workers inside each pod — two stable, connection-level layers, no primary in the data path at either level. Kubernetes keeps what it is unmatched at: placement, fleet rolls, cross-pod routing, horizontal scale. The embedded supervisor takes the row the platform cannot see, and fills the cores you already reserved.
(When 1-vCPU pods genuinely fit the service, the kernel path buys nothing — see When this topology is the wrong choice.)
Processes or threads?
Credit where due: Platformatic’s work on Watt
is what brought SO_REUSEPORT into Node application serving, and it is the
direct inspiration for ClusterKit. The two projects diverge on the isolation
axis, and that divergence is a genuine fork in the road.
Watt runs each application in worker threads inside a single runtime process —
one V8 isolate per application — optimized for composition: frontend, API, and
database API deployed as one unit, with inter-application calls routed over
MessagePort instead of TCP. It also supports SO_REUSEPORT for entrypoint
scaling. Its own documentation points to “completely isolated processes” when
that is what your architecture needs.
ClusterKit went the other direction: child processes via node:cluster, one
application per orchestrator, zero runtime dependencies, no daemon, no config
file.
The trade-off is failure containment:
- Threads share a process. A native-module segfault or an OOM kill ends the runtime — all applications, all workers.
- Child processes are contained. A crashed worker is replaced by the supervisor while the rest of the fleet keeps serving; the OOM killer takes one worker, not the fleet.
Neither is wrong. If your risk profile is “several apps that must ship and scale together”, the thread runtime is the right tool. If it is “one app that must survive its own crashes on a machine it shares with nothing else”, the boring choice is processes. Choose by failure mode, not by feature list.
What it looks like when it works
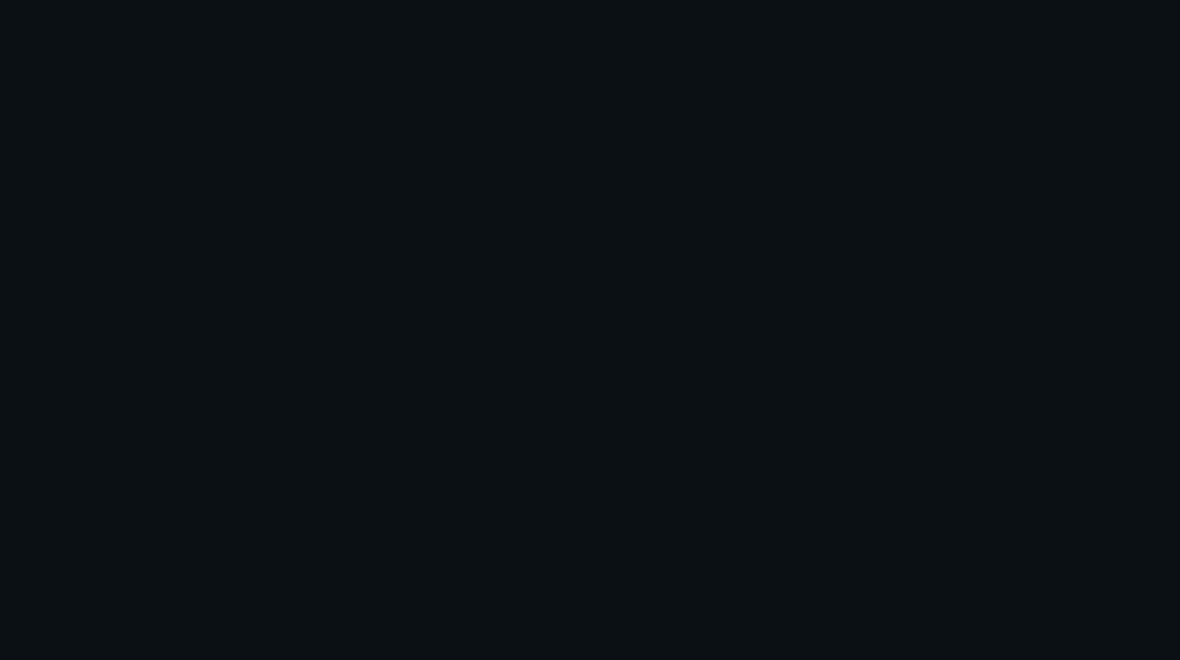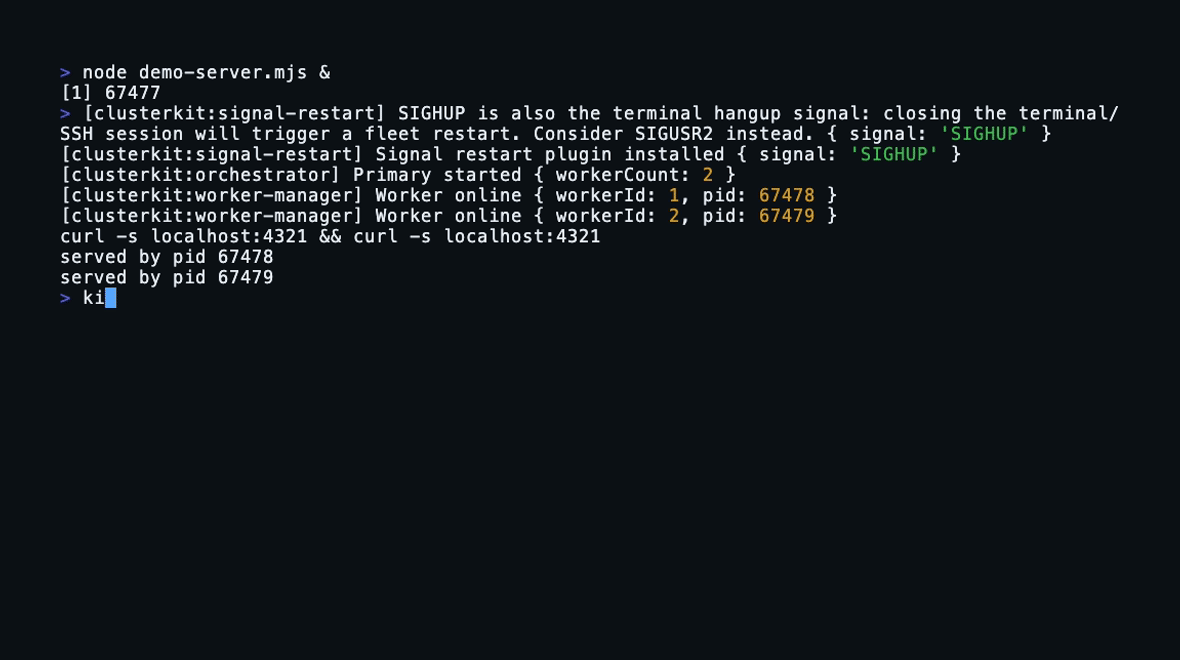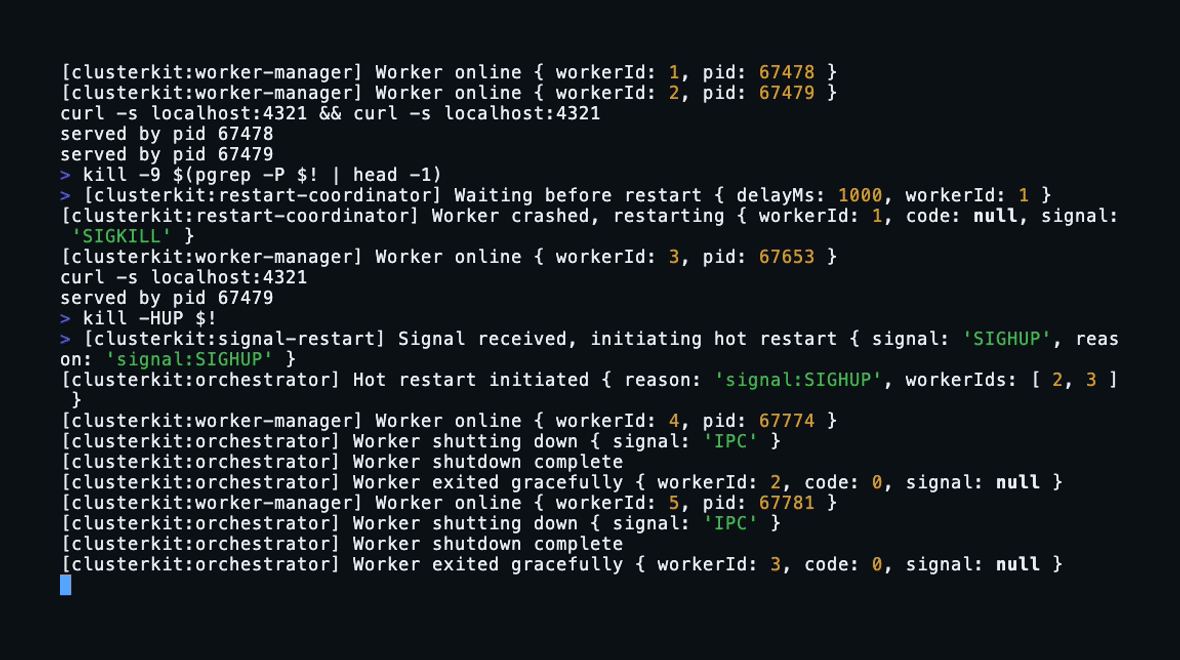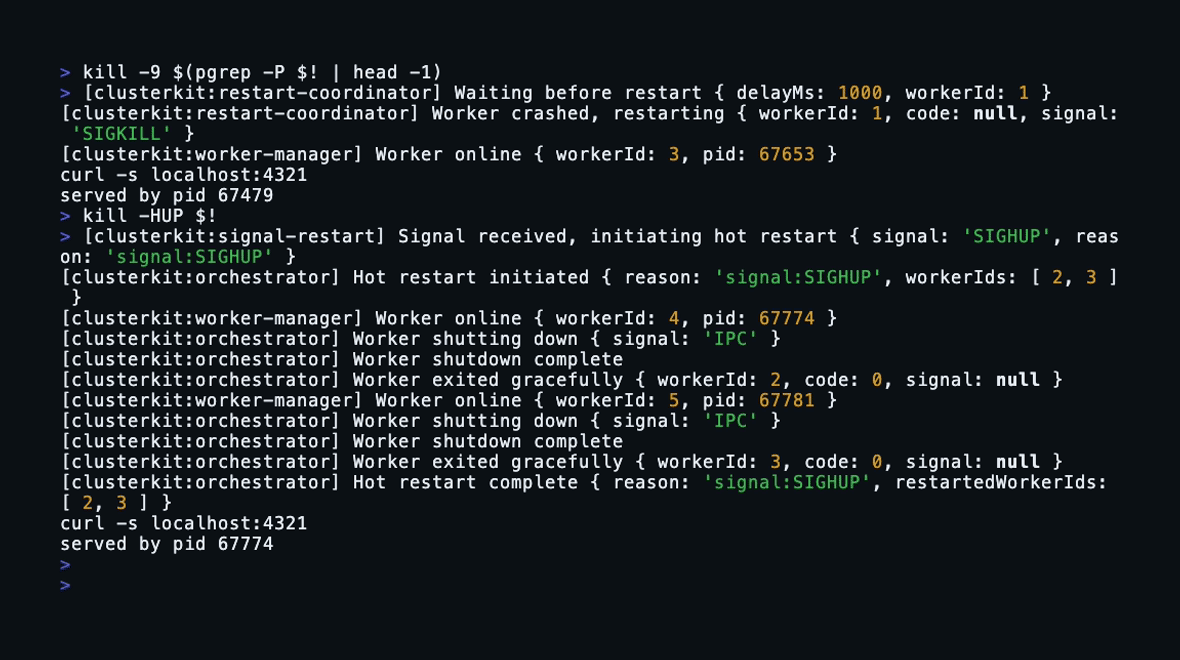
Two workers boot, one is killed with SIGKILL, the supervisor replaces it with
backoff, then kill -HUP rolls the whole fleet with zero dropped connections:
The code behind it — the full getting-started is 15 lines:
import { createServer } from "node:http";
import { Orchestrator } from "@goopil/clusterkit";

const orchestrator = new Orchestrator({ logger: console });

// Runs in every worker process
orchestrator.run(async ({ listen, shutdown }) => {
  const server = createServer((_req, res) => {
    res.end(`hello from pid ${process.pid}`);
  });

  // SO_REUSEPORT on Linux, cluster IPC elsewhere — decided for you
  const bound = listen(server);
  shutdown(() => bound.close());
});
Everything measured below is supervision added around this pattern: backoff and a circuit breaker for crash loops, ACK-based drain for shutdown, rolling restart for replacement, opt-in health heartbeats for wedged workers, cgroup-aware sizing for containers. Prometheus and OTLP export exist as plugins; none of it is a runtime dependency beyond the one package.
The numbers, with their caveats
Method: Docker node:22-slim, linux arm64, 4 vCPU cap; autocannon, 10 s warmup
- 30 s measure, median of 3 runs; 150 connections (50 per worker). Full data and methodology in BENCHMARKS.md.
Hello-world workload (trivial JSON — pure orchestrator overhead):
| Orchestrator | Req/sec | Boot | Shutdown | RSS (tree avg) |
|---|---|---|---|---|
| clusterkit-3 | 43,954 | 204 ms | 35 ms | 193 MB |
| native-cluster-3 | 44,615 | 205 ms | 10 ms | 195 MB |
| native-cluster-3 + SO_REUSEPORT | 45,728 | 207 ms | 3 ms | 191 MB |
| throng-3 | 41,030 | 2 ms | 29 ms | 204 MB |
| pm2-3 (cluster mode) | 38,222 | 508 ms | 228 ms | 406 MB |
The shutdown column needs one footnote: clusterkit’s 35 ms includes the ACK protocol that guarantees in-flight requests complete before exit; native
cluster’s 10 ms is a rawSIGTERMwith no such guarantee.
Three honest readings:
- An embedded library is not free, but it is close. ClusterKit costs ~1.5%
vs raw
clusteron trivial workloads and wins 4 of 8 workloads across the suite; the other gaps sit within run-to-run variance. The worst measured deficit (cpu-io-mix, −13.7%) comes from one noisy sample set — its best-case run matches native. - The dispatch topology itself is worth +2–4%, not 3x.
SO_REUSEPORTvs IPC round-robin: ahead on 5 of 8 workloads, up to +4.2%. The kernel path buys topology properties first, throughput second. - The daemon tax is the real story. pm2 on the same workload: +110% resident memory, +60% CPU, 2.5x boot time, 6.5x shutdown time, −13% throughput.
Recovery — the number that actually matters for this topology: SIGKILL 2 of 3
workers under load, then poll over fresh connections until every worker slot
answers again. Full restore in ~3.6 s, 35 requests served in the degraded
window, zero timeouts. Restore time is dominated by deliberate restart backoff
(~1 s first replacement, ~3 s second) — that is the circuit breaker choosing
stability over speed, not latency you can tune away.
Caveats worth keeping: later workloads show inflated RSS/CPU from cumulative container memory pressure (sampler artifact); macOS runs are excluded (unreliable
SO_REUSEPORT, no/proc). These numbers are a baseline, not a sales pitch — rerun the suite on your hardware.
Coming from pm2
The migration is a config translation, not a rewrite:
| pm2 / throng | ClusterKit |
|---|---|
pm2 start app.js -i max | new Orchestrator().run(workerFn) — worker count from workers: 'auto' |
pm2 reload all | orchestrator.restartWorkers(), or kill -HUP with the signal-restart plugin |
| SIGINT / stop hooks | shutdown(callback) — ACK protocol, SIGTERM → SIGINT → SIGKILL escalation |
ecosystem.config.js | the Orchestrator config object — typed and validated at startup |
pm2 logs | any logger via logger: (console, pino, winston…) |
pm2 monit / pm2.io | @goopil/clusterkit-prometheus + a bundled Grafana dashboard |
WEB_CONCURRENCY (Heroku-style) | honored by workers: 'auto' |
When this topology is the wrong choice
- Single-CPU containers with horizontal autoscaling.
SO_REUSEPORTis per-host. On a 1-vCPU pod the kernel path buys nothing; scale at the pod layer instead. - Multi-application composition. One runtime serving frontend + API + database API is an application-server problem — that is Watt’s ground, and it is good at it.
- macOS and Windows as serving targets.
SO_REUSEPORTis Linux-reliable. On macOS it is flaky enough that ClusterKit disables it and requiresWEB_CONCURRENCYfor multi-worker mode. Develop on macOS, serve from Linux.
Closing
The kernel solves connection dispatch; it has solved it since Linux 3.9. Everything that made people adopt daemons — crash policy, drain, health, sizing — was never about dispatch. It is supervision, and it belongs next to the code it supervises, not in an external process.
In a Kubernetes pod this composes as three layers with three jobs: the platform supervises the container, the kernel balances the connections, the embedded supervisor fills the cores and replaces the crashed ones.
ClusterKit is my attempt at making that decision boring: one dependency-free
call in main(), the fleet handled. The repo is
github.com/Goopil/clusterkit — and if
the trade-off analysis above saved you an evaluation, a ⭐ is the main discovery
signal for an independently developed library.